The basis of this project is a large corpus of speeches given by Charles Dickens throughout his life. The specific dataset I worked with was published by Project Gutenberg and is available online for free. It is squarely in the public domain and can be saved, copied, and distributed at will. This made it easy to work with, as I could simply download the 211-page file and begin cleaning it up for my purposes.
The publication of Dickens’s speeches included many descriptions and notes about their contexts. These were written in 3rd person and were clearly not written by him. Thankfully, they were each contained within square brackets and rather easy to clean up. It took a simple find-in-document function (and a few focused minutes) to remove all of the excess text. We are not interested in words not spoken by Dickens, after all.
In order to see a trend across time, the corpus needed to be split into “documents.” While one might first think to divide it into the individual speeches, the sheer number of them would clutter the visualization. Fortunately, Voyant Tools is able to intelligently divide the corpus into any given number of pieces. I decided on 10, as that seemed like a number high enough to see significant variation but still low enough to avoid overspecification.
Further analysis of this newly cleaned data can be found on the Visualizations page.
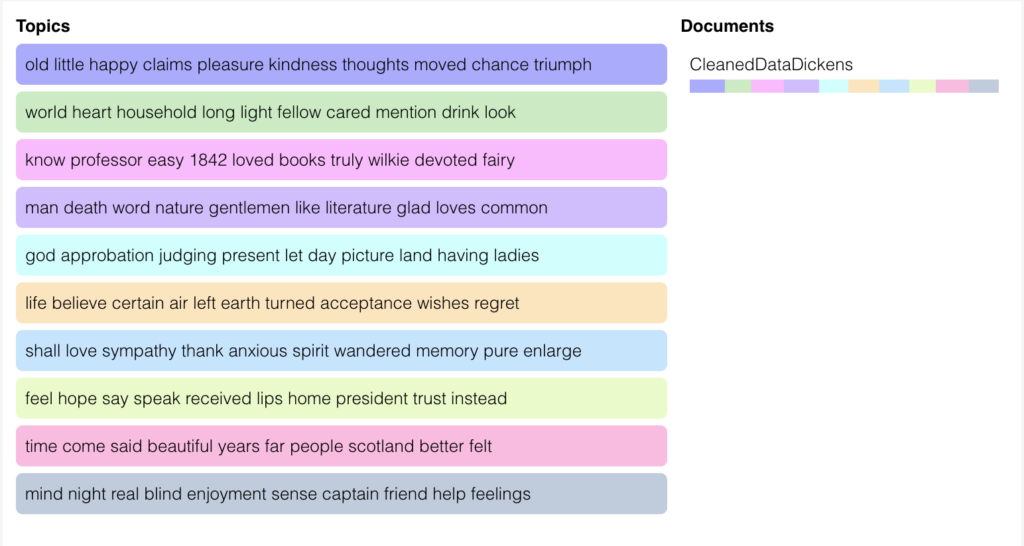
likely relevant to the larger ideas of each document segment.
